
1.
What's running
State, step, iteration, and spend for every agent, live.
2.
What's blocked
Every decision waiting on a person, with a name on it.
3.
What was decided
Every intervention kept as a node the next agent reads.
Built with the people who run the work


The problem
Every agent framework makes the AI better at the work. None make you better at driving it.
Agent frameworks assume the human steps out. Sentinel assumes they never do. You review outputs, monitor runs, make the calls only you can make, set priorities, and supply the context that lives nowhere but your head. That work is real, and today it has no home — the decision is in a Slack thread, the reasoning is in a meeting transcript nobody reads, the constraint was agreed on a call, the spec is a doc, the state is in GitHub, and the question is buried in your inbox. Six things break, and they break in a predictable order.
01
Nobody knows what the agents are doing
Runs happen inside the harness and write to a log nobody opens. You find out an agent got it wrong from a customer, not from a test.
02
Agents stop without telling anyone
An agent crashes, times out, or loses its machine. Nothing announces it. The ticket still says an agent is working on it, three days later.
03
Questions land in a channel, not on a person
An agent needs a decision only a person can make, so it posts in Slack. Whoever is awake replies. Nobody owns it, nobody logs it, and the next agent never learns what was decided.
04
Agents wait for no reason, and collide anyway
You cap how many run at once, so agents working on unrelated files sit idle. The two that are editing the same file still run straight into each other.
05
Agents start work that isn’t ready
One task has to finish before another can start, but nothing records that. So agents build against a half-finished migration, and someone orders the board by hand every morning.
06
Every agent reads the whole knowledge base
One flat store means each agent loads all of it, every time. It costs more, it gets slower, and the more you add the less the agent finds what matters.
01 / Observability
You can’t oversee what you can’t see.
An agent fleet fails quietly. Nothing throws, nothing pages, and the first signal is a customer. Being accountable for that fleet means seeing three things at once — what each agent is doing, what it’s reasoning from, and what a person already told it.
What it’s doing
The run, while it’s still running
State, current step, iterations against the cap it declared, spend so far. Live, per agent, without opening a terminal.
Assemble · Reason · Act · Observe
Iteration 3 of 8 · $0.41 · 00:11
What it’s drawing on
The context behind the answer
Which knowledge nodes, which files, which earlier decisions went into this iteration. When an agent gets something wrong, this is where you find out why.
6 nodes loaded, not 412
Every source named, per step
Who has touched it
The human half of the run
Every question the agent asked, who answered it, when, and what it did next. The people part of the work is in the record, not in a thread nobody can find.
Asked, answered, resumed — timestamped
Rated 4.6 / 5 by a named person
Eight agents in one view with state, loop step, iteration, spend and eval score.
Quality stops being asserted and starts being measured — and the failure you can’t see stops being the one that costs you.

02 / Durable runs
A run that stops should not start over.
An agent that hits its limit, crashes, or waits too long usually does one thing: it starts again from the beginning. That’s tolerable when the only cost is tokens. It stops being tolerable the moment a person is involved.
Because the run doesn’t just lose its own work. It loses yours. The question you answered an hour ago gets asked again. The constraint you explained gets explained again. The decision you already made is made again, possibly differently. You did the work, and the system threw it away.
That’s how people learn to stop answering. And an agent whose questions go unanswered is an agent that starts guessing.
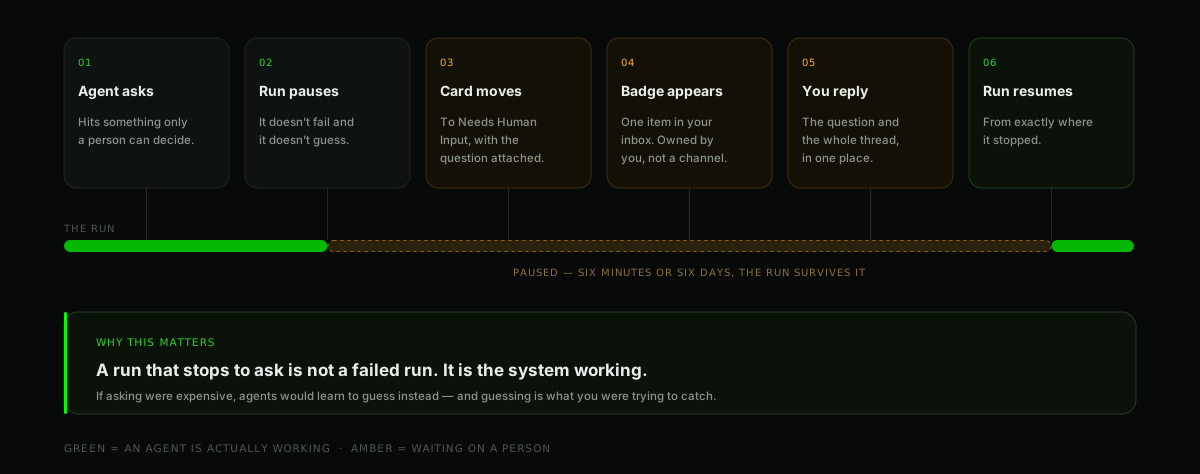
Sentinel’s loops hold their place. A run that pauses for a person keeps everything it had — its context, its plan, the step it was on — for six minutes or six days. When you reply, it picks up at the next step, not the first one. Nothing you contributed has to be contributed twice.
That’s not a technical nicety. It’s the difference between working with something and restarting a conversation with it every morning.
A pause costs no progress. Six minutes or six days.
Resumes at the step it stopped on, never at step one.
Your answer is kept, and reused by the next agent that needs it.
Every loop declares where it stops, so nothing runs away.


The loop
Durable by construction, and it always knows how to stop.
Every loop has three strict parts: an initialisation that fixes the objective, constraints, and starting variables; an iteration body; and a termination condition that prevents infinite loops and runaway cost.
01
Assemble
Pull the scoped subtree of context this iteration needs, and nothing beyond it.
02
Reason
Decide the next action against the objective and the guardrails it was given.
03
Act
Call a verified connector, or open a human gate and pause durably.
04
Observe
Score the result, write back what was learned, and check the termination condition.
ENFORCED
Iteration cap
Every loop declares one up front. There is no unbounded run.
ENFORCED
Spend ceiling
Counted per run and visible while it’s still counting.
ENFORCED
Human gate
A durable pause. Six minutes or six days, the run survives it.
ENFORCED
Eval gate
Scored against the step’s output, human-ranked, fed back in.
Who it’s for
Agents aren't assistants. They're headcount.
Team Issue
The person accountable when an agent gets it wrong
Eng lead, ops lead, head of automation. When an agent gets it wrong, it lands on them — and they had no way to see it coming.
The bottleneck is not
Model quality
The bottleneck is
Coordination, oversight, and trust
Solution
The sentinel
Reviews, decides, answers, rates. Wants fewer interruptions, not another dashboard.
03 / Decisions
You answer once. The next agent asks again.
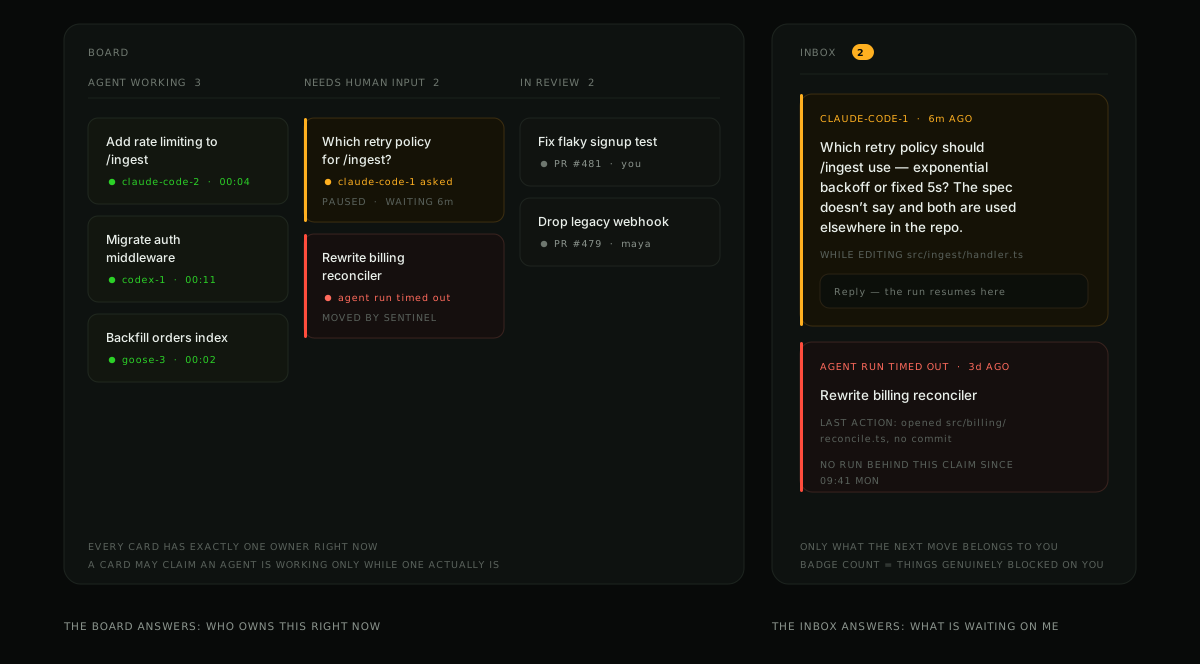
An agent hits a fork it can't decide and pings a channel. The question arrives with no context, so answering it takes longer than the decision does. And when you do answer, it goes nowhere — not to the run, not to the knowledge base. The next agent asks the same thing. The board shows every piece of work and who owns it right now. The inbox holds only what's waiting on you, each request carrying what the agent tried, what it read, and what it's about to do. You reply, the run resumes, and your reasoning is written back as a node — so the next agent starts with the answer instead of asking for it.
Board — every piece of work, one owner, human or agent.
Inbox — only what’s blocked on you, with the context attached.
Replying resumes the run. No restart, no re-explaining.
Your answer becomes a node the next agent reads.
04 / Fleet
Concurrency managed by what the work touches.
Every agent publishes its plan and what it intends to touch. Two agents heading for the same code area get serialised; six agents on six unrelated repos don’t. A number in a config file can’t tell those apart.
Agents claim what they’re about to touch, before they touch it.
A conflict is caught before the edit, not in the merge.
The second agent waits, then resumes. It isn’t killed.
Humans see the same claims the agents do.

Connect your stack
Monitoring, code, observability, cloud, CI/CD systems, messaging, and even homegrown tooling.
" width="24px"><path d="M 0 0 L 24 0 L 24 24 L 0 24 Z" fill="transparent" height="24px" id="DuhZHebCq" width="24px"/><path d="M 7.858 0 L 10.576 1.257 L 10.228 4.38 L 5.369 9.885 C 2.487 8.033 0.533 5.037 0 1.653 Z" fill="rgb(21, 227, 255)" height="9.885000000000002px" id="JJEAJseCd" transform="translate(0 12.212)" width="10.576px"/><path d="M 5.682 1.305 L 9.317 7.568 C 7.3 8.986 4.894 9.745 2.428 9.741 C 1.612 9.741 0.799 9.659 0 9.495 L 0.8 2.332 L 2.858 0 Z" fill="rgb(52, 141, 252)" height="9.74101525885936px" id="rQgESjQWF" transform="translate(9.428 14.259)" width="9.316999999999997px"/><path d="M 9.929 0 C 10.187 0.98 10.325 2.009 10.325 3.07 C 10.325 5.54 9.579 7.835 8.3 9.744 L 1.577 6.635 L 0 3.919 L 1.982 1.673 Z" fill="rgb(253, 72, 115)" height="9.744px" id="oy2ZO1kid" transform="translate(13.533 8.929)" width="10.325px"/><path d="M 0.969 0 C 4.449 0.061 7.73 1.633 9.958 4.307 L 4.403 10.602 L 1.476 11.218 L 0 8.674 Z" fill="rgb(255, 199, 0)" height="11.218px" id="Am8Bk4LNT" transform="translate(11.111 0)" width="9.957999999999998px"/><path d="M 10.802 7.534 L 10.476 10.455 L 7.55 11.071 L 0 7.58 C 0.951 4.245 3.294 1.482 6.43 0 Z" fill="rgb(0, 231, 185)" height="11.071px" id="gQ5F0q2E4" transform="translate(0.309 1.141)" width="10.802px"/></g></svg>)
" width="28px"><path d="M 0 0 L 28 0 L 28 22 L 0 22 Z" fill="transparent" height="22px" id="QvGAEMl33" width="28px"/><path d="M 9.714 0 C 10.03 0 10.286 0.246 10.286 0.55 L 10.286 4.618 C 10.286 4.741 10.44 4.802 10.53 4.715 L 15.094 0.322 C 15.308 0.116 15.599 0 15.902 0 L 20.906 0 C 21.058 0 21.203 0.058 21.31 0.161 L 23.025 1.811 C 23.132 1.912 23.192 2.053 23.192 2.2 C 23.192 2.347 23.132 2.488 23.025 2.589 L 20.815 4.715 C 20.725 4.802 20.789 4.95 20.916 4.95 L 25.478 4.95 C 25.629 4.95 25.775 5.008 25.882 5.111 L 27.596 6.761 C 27.703 6.862 27.764 7.003 27.764 7.15 C 27.764 7.297 27.703 7.438 27.596 7.539 L 25.345 9.706 C 25.292 9.757 25.262 9.827 25.262 9.9 C 25.262 9.973 25.292 10.043 25.345 10.094 L 27.192 11.872 C 27.709 12.37 28 13.046 28 13.75 C 28 14.454 27.71 15.13 27.192 15.628 L 20.906 21.678 C 20.688 21.886 20.399 22.001 20.098 22 L 18.286 22 C 18.137 22.003 17.993 21.947 17.886 21.843 C 17.779 21.74 17.717 21.599 17.714 21.45 L 17.714 17.382 C 17.714 17.259 17.56 17.198 17.47 17.285 L 12.906 21.678 C 12.688 21.886 12.399 22.001 12.098 22 L 7.094 22 C 6.944 22 6.799 21.943 6.69 21.839 L 4.975 20.189 C 4.868 20.088 4.808 19.947 4.808 19.8 C 4.808 19.653 4.868 19.512 4.975 19.411 L 7.185 17.285 C 7.275 17.198 7.211 17.05 7.084 17.05 L 2.522 17.05 C 2.372 17.05 2.227 16.993 2.118 16.889 L 0.404 15.239 C 0.297 15.138 0.236 14.997 0.236 14.85 C 0.236 14.703 0.297 14.562 0.404 14.461 L 2.655 12.294 C 2.708 12.243 2.738 12.173 2.738 12.1 C 2.738 12.027 2.708 11.957 2.655 11.906 L 0.808 10.128 C 0.294 9.638 0.002 8.96 0 8.25 C 0 7.546 0.29 6.87 0.808 6.372 L 7.094 0.322 C 7.308 0.116 7.599 0 7.902 0 Z M 11.469 4.95 C 10.711 4.95 9.985 5.24 9.449 5.756 L 3.345 11.63 C 3.165 11.803 3.292 12.099 3.547 12.099 L 11.882 12.099 C 12.136 12.099 12.264 12.395 12.084 12.569 L 7.916 16.579 C 7.736 16.753 7.864 17.049 8.118 17.049 L 16.531 17.049 C 17.289 17.049 18.016 16.759 18.551 16.243 L 24.655 10.368 C 24.824 10.206 24.722 9.936 24.499 9.902 L 24.453 9.899 L 16.118 9.899 C 15.864 9.899 15.736 9.603 15.916 9.429 L 20.084 5.419 C 20.264 5.245 20.136 4.949 19.882 4.949 L 11.469 4.949 Z" fill="rgb(41, 122, 255)" height="22.00011007384878px" id="X6OpbA7xi" transform="translate(0 0)" width="28px"/></g></svg>)
" width="24px"><path d="M 0 0 L 24 0 L 24 24 L 0 24 Z" fill="transparent" height="24px" id="yDBNM6rU9" width="24px"/><path d="M 12.654 19.523 C 12.654 20.052 12.517 20.574 12.253 21.048 C 12.024 21.457 11.89 21.903 11.858 22.36 L 11.782 23.455 L 11.706 22.36 C 11.674 21.903 11.539 21.458 11.311 21.048 C 11.047 20.574 10.909 20.053 10.909 19.523 L 10.909 3.933 C 10.91 3.399 11.049 2.874 11.311 2.408 C 11.538 2.005 11.673 1.556 11.706 1.095 L 11.782 0 L 11.858 1.095 C 11.891 1.556 12.026 2.005 12.253 2.408 C 12.517 2.881 12.654 3.403 12.654 3.933 Z M 7.889 3.971 C 8.153 4.445 8.291 4.967 8.291 5.496 L 8.291 17.959 C 8.291 18.489 8.153 19.011 7.889 19.484 C 7.663 19.887 7.528 20.336 7.495 20.797 L 7.418 21.891 L 7.342 20.796 C 7.309 20.335 7.174 19.887 6.947 19.484 C 6.685 19.018 6.547 18.493 6.546 17.959 L 6.546 5.496 C 6.546 4.967 6.683 4.445 6.947 3.971 C 7.176 3.562 7.31 3.116 7.342 2.659 L 7.418 1.564 L 7.495 2.659 C 7.527 3.116 7.661 3.562 7.889 3.971 Z M 6.109 16.396 C 6.109 16.925 5.971 17.447 5.707 17.92 C 5.481 18.323 5.346 18.772 5.313 19.233 L 5.236 20.328 L 5.16 19.233 C 5.128 18.776 4.994 18.33 4.765 17.92 C 4.501 17.447 4.364 16.925 4.364 16.395 L 4.364 7.06 C 4.365 6.526 4.503 6.001 4.765 5.535 C 4.992 5.132 5.127 4.684 5.16 4.223 L 5.236 3.128 L 5.313 4.223 C 5.346 4.684 5.481 5.132 5.707 5.535 C 5.972 6.008 6.109 6.531 6.109 7.061 Z M 3.525 8.662 C 3.79 9.136 3.927 9.658 3.927 10.187 L 3.927 13.268 C 3.927 13.798 3.79 14.32 3.525 14.793 C 3.299 15.196 3.164 15.645 3.131 16.106 L 3.055 17.201 L 2.978 16.106 C 2.945 15.645 2.81 15.196 2.584 14.793 C 2.322 14.327 2.183 13.802 2.182 13.268 L 2.182 10.188 C 2.182 9.658 2.319 9.136 2.584 8.662 C 2.812 8.253 2.946 7.807 2.978 7.35 L 3.055 6.255 L 3.131 7.35 C 3.163 7.807 3.297 8.253 3.525 8.662 Z M 0.402 10.226 C 0.628 9.823 0.763 9.375 0.796 8.914 L 0.873 7.819 L 0.949 8.914 C 0.982 9.375 1.117 9.823 1.344 10.226 C 1.602 10.685 1.74 11.202 1.745 11.728 C 1.741 12.25 1.604 12.763 1.344 13.23 C 1.115 13.639 0.981 14.085 0.949 14.542 L 0.873 15.637 L 0.796 14.542 C 0.764 14.085 0.63 13.639 0.402 13.23 C 0.141 12.763 0.004 12.249 0 11.728 C 0.004 11.206 0.142 10.692 0.402 10.226 Z M 10.07 2.408 C 10.335 2.881 10.473 3.403 10.473 3.933 L 10.473 19.523 C 10.473 20.053 10.335 20.574 10.071 21.048 C 9.842 21.458 9.708 21.903 9.676 22.36 L 9.6 23.455 L 9.524 22.36 C 9.491 21.899 9.356 21.451 9.129 21.048 C 8.867 20.582 8.728 20.057 8.727 19.523 L 8.727 3.933 C 8.727 3.403 8.865 2.881 9.129 2.408 C 9.358 1.998 9.492 1.552 9.524 1.095 L 9.6 0 L 9.676 1.095 C 9.708 1.552 9.842 1.998 10.071 2.408 Z M 14.434 2.408 C 14.699 2.881 14.836 3.403 14.836 3.933 L 14.836 19.523 C 14.836 20.053 14.699 20.574 14.435 21.048 C 14.206 21.458 14.072 21.903 14.04 22.36 L 13.964 23.455 L 13.887 22.36 C 13.854 21.899 13.719 21.451 13.493 21.048 C 13.231 20.582 13.092 20.057 13.091 19.523 L 13.091 3.933 C 13.091 3.403 13.228 2.881 13.493 2.408 C 13.719 2.005 13.854 1.556 13.887 1.095 L 13.964 0 L 14.04 1.095 C 14.072 1.552 14.206 1.998 14.435 2.408 Z M 17.018 17.959 C 17.018 18.489 16.881 19.011 16.616 19.484 C 16.39 19.887 16.255 20.335 16.222 20.796 L 16.145 21.891 L 16.069 20.797 C 16.037 20.34 15.903 19.894 15.675 19.484 C 15.41 19.011 15.273 18.489 15.273 17.959 L 15.273 5.496 C 15.274 4.962 15.413 4.437 15.675 3.971 C 15.901 3.568 16.036 3.12 16.069 2.659 L 16.145 1.564 L 16.222 2.659 C 16.255 3.12 16.39 3.568 16.616 3.971 C 16.881 4.445 17.018 4.967 17.018 5.496 Z M 18.798 5.535 C 19.062 6.008 19.2 6.531 19.2 7.06 L 19.2 16.395 C 19.2 16.925 19.062 17.447 18.798 17.92 C 18.572 18.323 18.437 18.772 18.404 19.233 L 18.327 20.328 L 18.251 19.233 C 18.218 18.772 18.083 18.323 17.856 17.92 C 17.594 17.455 17.456 16.93 17.454 16.396 L 17.454 7.06 C 17.454 6.53 17.592 6.008 17.856 5.535 C 18.085 5.125 18.219 4.679 18.251 4.223 L 18.327 3.128 L 18.404 4.223 C 18.436 4.679 18.57 5.126 18.798 5.535 Z M 21.382 13.268 C 21.382 13.798 21.244 14.32 20.98 14.793 C 20.751 15.202 20.617 15.649 20.585 16.106 L 20.509 17.201 L 20.433 16.106 C 20.401 15.649 20.267 15.203 20.038 14.793 C 19.774 14.32 19.636 13.798 19.636 13.268 L 19.636 10.187 C 19.637 9.653 19.776 9.128 20.038 8.662 C 20.265 8.259 20.4 7.811 20.433 7.35 L 20.509 6.255 L 20.585 7.35 C 20.618 7.811 20.753 8.259 20.98 8.662 C 21.244 9.136 21.382 9.657 21.382 10.187 Z M 21.818 11.728 C 21.818 11.728 21.818 11.728 21.818 11.729 C 21.818 11.729 21.818 11.729 21.818 11.729 Z M 21.818 11.729 C 21.818 11.729 21.818 11.729 21.818 11.729 Z M 21.818 11.729 C 21.822 11.207 21.96 10.693 22.22 10.227 C 22.447 9.824 22.582 9.376 22.615 8.915 L 22.691 7.82 L 22.767 8.915 C 22.8 9.376 22.935 9.824 23.162 10.227 C 23.42 10.686 23.559 11.202 23.564 11.729 C 23.56 12.251 23.422 12.764 23.162 13.231 C 22.933 13.64 22.799 14.086 22.767 14.543 L 22.691 15.638 L 22.615 14.543 C 22.583 14.086 22.449 13.64 22.22 13.231 C 21.96 12.764 21.822 12.25 21.818 11.729 Z" fill="rgb(255, 255, 255)" height="23.455000000000002px" id="Tf7dzF3Vd" transform="translate(0 0.272)" width="23.564000793457033px"/></g></svg>)
" width="26.00005485166302px"><path d="M 0 0 L 26 0 L 26 22 L 0 22 Z" fill="transparent" height="22px" id="bHpDrmTYu" transform="translate(0 0)" width="26px"/><path d="M 19.842 22 C 23.255 21.928 26 19.034 26 15.476 C 26.005 13.758 25.345 12.105 24.158 10.863 L 13.684 0 L 13.684 6.752 C 13.681 7.873 14.112 8.952 14.887 9.763 L 17.34 12.308 L 17.347 12.315 L 21.461 16.582 C 21.595 16.723 21.595 16.943 21.461 17.084 C 21.398 17.151 21.311 17.188 21.219 17.188 C 21.127 17.188 21.04 17.151 20.977 17.084 L 19.559 15.613 L 6.44 15.613 L 5.022 17.083 C 4.959 17.15 4.872 17.187 4.78 17.187 C 4.688 17.187 4.601 17.15 4.538 17.083 C 4.405 16.943 4.405 16.722 4.538 16.582 L 8.652 12.315 L 8.659 12.308 L 11.112 9.763 C 11.887 8.953 12.318 7.874 12.315 6.753 L 12.315 0 L 1.842 10.863 C 0.655 12.105 -0.005 13.758 0 15.476 C 0 19.034 2.745 21.928 6.158 22 Z" fill="rgb(255, 10, 10)" height="22px" id="FVH0wOdTn" transform="translate(0 0)" width="26.00005485166318px"/></g></svg>)
" width="26px"><path d="M 0 0 L 26 0 L 26 26 L 0 26 Z" fill="transparent" height="26px" id="X3NihXcda" width="26px"/><path d="M 13 0 C 17.092 0 20.945 1.927 23.4 5.2 L 13 5.2 C 8.692 5.2 5.2 8.692 5.2 13 L 13 13 L 23.992 6.058 C 24.808 7.351 25.39 8.777 25.711 10.272 L 20.8 13 L 26 13 L 25.996 13.323 C 25.858 18.858 22.231 23.698 16.957 25.383 C 11.684 27.068 5.922 25.229 2.6 20.8 L 13 20.8 C 17.157 20.8 20.584 17.539 20.79 13.387 L 20.8 13 L 13 13 L 2.008 19.941 C 1.192 18.648 0.611 17.222 0.291 15.727 L 5.2 13 L 0 13 C 0 5.82 5.82 0 13 0 Z" fill="rgb(83, 58, 253)" height="26.000821894877653px" id="FL6mDyX0W" width="26px"/></g></svg>)
" width="26.000042373657564px"><path d="M 0 0 L 26 0 L 26 18 L 0 18 Z" fill="transparent" height="18px" id="UQVo2BFOR" transform="translate(0 0)" width="26px"/><path d="M 4.407 6.819 L 24.689 12.314 C 25.462 12.524 26 13.237 26 14.054 L 26 18 L 21.593 18 L 21.593 16.13 L 13 13.804 L 4.407 16.13 L 4.407 18 L 0 18 L 0 14.054 C 0 13.237 0.538 12.524 1.31 12.314 L 4.407 11.474 L 1.311 10.636 C 0.532 10.418 -0.005 9.705 0 8.896 L 0 6.3 C 0 5.306 0.79 4.5 1.763 4.5 L 4.407 4.5 Z M 24.237 4.5 C 25.211 4.5 26 5.306 26 6.3 L 26 9 L 21.593 9 L 21.593 4.5 Z M 19.83 0 C 20.804 0 21.593 0.806 21.593 1.8 L 21.593 4.5 L 4.407 4.5 L 4.407 1.8 C 4.407 0.806 5.196 0 6.17 0 Z" fill="rgb(11, 220, 133)" height="18px" id="WzLEVCYzH" transform="translate(0 0)" width="26.000042373657227px"/></g></svg>)
" width="26px"><path d="M 0 0 L 26 0 L 26 26 L 0 26 Z" fill="transparent" height="26px" id="o5YanBthv" width="26px"/><path d="M 12.984 0 C 20.164 0 25.984 5.82 25.984 13 L 25.984 22.1 C 25.984 24.254 24.238 26 22.084 26 L 13.634 26 L 13.634 20.297 C 13.634 18.996 13.714 17.647 14.396 16.54 C 15.384 14.934 17.022 13.836 18.883 13.532 L 19.133 13.492 C 19.343 13.42 19.485 13.222 19.485 13 C 19.485 12.778 19.343 12.58 19.133 12.508 L 18.883 12.468 C 16.127 12.018 13.966 9.857 13.516 7.101 L 13.476 6.851 C 13.405 6.64 13.207 6.497 12.984 6.497 C 12.761 6.497 12.563 6.64 12.492 6.851 L 12.452 7.101 C 12.148 8.962 11.05 10.6 9.444 11.588 C 8.336 12.271 6.988 12.35 5.687 12.35 L 0 12.35 C 0.34 5.472 6.023 0 12.984 0 Z" fill="rgb(240, 98, 37)" height="26px" id="Ppg_huvd8" transform="translate(0.016 0)" width="25.984px"/><path d="M 0 13.65 L 5.703 13.65 C 7.004 13.65 8.353 13.73 9.46 14.412 C 10.326 14.945 11.055 15.674 11.588 16.54 C 12.271 17.648 12.35 18.996 12.35 20.297 L 12.35 26 L 3.9 26 C 1.746 26 0 24.254 0 22.1 Z M 26 1.3 C 26 2.018 25.418 2.6 24.7 2.6 C 23.982 2.6 23.4 2.018 23.4 1.3 C 23.4 0.582 23.982 0 24.7 0 C 25.418 0 26 0.582 26 1.3 Z" fill="rgb(240, 98, 37)" height="25.999999618530275px" id="TnatFIGDw" transform="translate(0 0)" width="25.999999618530275px"/></g></svg>)
" width="30px"><path d="M 0 0 L 30 0 L 30 12 L 0 12 Z" fill="transparent" height="12px" id="KIfaXk_Vj" width="30px"/><path d="M 7.307 0 L 15.769 0 L 8.461 12 L 0 12 Z" fill="rgb(255, 122, 0)" height="12px" id="eQffSRv3T" transform="translate(14.039 0)" width="15.769px"/><path d="M 7.308 0 L 13.462 0 L 6.154 12 L 0 12 Z" fill="rgb(255, 151, 54)" height="12px" id="wj93pOTXv" transform="translate(6.346 0)" width="13.462px"/><path d="M 7.308 0 L 11.923 0 L 4.616 12 L 0 12 Z" fill="rgb(255, 188, 125)" height="12px" id="YzRUOUK7L" transform="translate(0.192 0)" width="11.923px"/></g></svg>)
" width="26px"><path d="M 0 0 L 26 0 L 26 26 L 0 26 Z" fill="transparent" height="26px" id="UqJgClpbA" width="26px"/><path d="M 19.5 18.2 L 19.5 7.8 C 19.5 7.082 18.918 6.5 18.2 6.5 L 18.135 6.5 C 17.79 6.5 17.459 6.636 17.215 6.88 L 6.881 17.216 C 6.637 17.46 6.5 17.791 6.5 18.136 L 6.5 26 L 0 26 L 0 18.135 C 0 16.066 0.822 14.082 2.285 12.619 L 12.619 2.285 C 14.082 0.822 16.066 0 18.135 0 L 18.2 0 C 22.508 0 26 3.492 26 7.8 L 26 18.2 C 26 22.508 22.508 26 18.2 26 L 9.1 26 L 9.1 19.5 L 18.2 19.5 C 18.918 19.5 19.5 18.918 19.5 18.2 Z M 0 0 L 11.05 0 L 4.55 6.5 L 0 6.5 Z" fill="rgb(46, 182, 125)" height="26px" id="DFlCBmh8Q" transform="translate(0 0)" width="26px"/></g></svg>)
" width="28.000001773900976px"><path d="M 0 0 L 28 0 L 28 18 L 0 18 Z" fill="transparent" height="18px" id="cOLp0JneC" transform="translate(0 0)" width="28px"/><path d="M 28 13.208 L 16.94 2.29 C 16.623 1.977 16.196 1.801 15.751 1.8 C 14.221 1.8 13.466 3.682 14.563 4.762 L 26.432 16.455 C 27.003 17.018 26.61 18 25.812 18 L 4.292 18 C 3.82 18 3.368 17.81 3.035 17.473 L 0.52 14.927 C 0.186 14.587 -0.001 14.13 0 13.654 L 0 4.792 L 11.06 15.71 C 11.377 16.024 11.804 16.2 12.249 16.2 C 13.779 16.2 14.534 14.318 13.437 13.238 L 1.568 1.545 C 0.997 0.982 1.39 0 2.188 0 L 23.708 0 C 24.18 0 24.632 0.19 24.965 0.527 L 27.479 3.073 C 27.813 3.41 28 3.868 28 4.346 Z" fill="rgb(253, 72, 115)" height="18px" id="N0zj6gN2L" transform="translate(0 0)" width="28.000001773900987px"/></g></svg>)
" width="26px"><path d="M 0 0 L 26 0 L 26 26 L 0 26 Z" fill="transparent" height="26px" id="aySJIqHM8" width="26px"/><path d="M 16.611 7.595 C 15.542 6.881 14.285 6.5 13 6.5 L 13 0 C 20.18 0 26 5.82 26 13 C 26 20.18 20.18 26 13 26 C 5.82 26 0 20.18 0 13 L 6.5 13 C 6.5 16.101 8.691 18.77 11.732 19.375 C 14.774 19.98 17.819 18.352 19.005 15.487 C 20.192 12.622 19.189 9.318 16.611 7.595 Z" fill="rgb(0, 125, 252)" height="26px" id="WtBlTcCtH" width="26px"/><path d="M 6.5 0 C 6.5 3.59 3.59 6.5 0 6.5 L 0 13 C 3.448 13.001 6.755 11.631 9.193 9.193 C 11.631 6.755 13.001 3.448 13 0 Z" fill="rgb(0, 125, 252)" height="13.000000154116675px" id="X1ZxQJ38J" width="13.000000154116673px"/></g></svg>)
" height="27.99884804175999px" id="vO3ypKHss" transform="translate(4 2)" width="23.00194688367269px"/></svg>)
05 / Dependencies
Chain the work, and the board sequences itself.
A task that can’t start yet says so, and says what it’s waiting for. When the blocker lands, the next task is claimable in the same second — nobody has to be watching for it.
Dependencies are first-class on the board, not a comment.
Blocked tasks name their blocker, not just their state.
No agent starts work whose ground is still moving.
Independent branches run in parallel by default.

06 / Knowledge
Organized Knowledge
The knowledge base is a mind map of entities and their relationships. Each task maps to the nodes it needs and the super-nodes above them — which makes scope a permission boundary, not just a token saving.
Nodes and super-nodes, connected — not one flat store.
A task loads its subtree. Everything else is never read.
Answers from the inbox are written back as nodes.
Markdown and Mermaid, so context stays compact and diff-able.

Where it sits
The layer above your harness, not another harness.
Sentinel doesn’t write code and doesn’t replace the runtime you already chose. Every harness will ship its own room. None of them will ship a neutral oversight layer above all of them.
Harness
Claude Code
Harness
Codex
Harness
goose
Harness
Your own


Questions
The things people ask first.
Humans and agents share the work. Sentinel watches over it.
All systems operational
99.98% UPTIME
Updates on new features and releases.
© 2026 Sudo Labs. All rights reserved.